Why Do OCR & Machine Translation Fail Without AI?
Why scripts fail differently, why OCR errors compound through translation, and what catches them first.
Japanese combines three writing systems on one page and should be a hard case for OCR. Benchmark research found the opposite: Japanese accuracy exceeds Latin script. Arabic and Hebrew are where things genuinely go wrong, for specific, documented reasons. Here is what real research shows about why scripts fail differently, and what actually stops the errors before translation compounds them.
Japanese combines three writing systems on the same page, Hiragana, Katakana, and Kanji, and by most intuitions that should be one of the harder cases for OCR. A recent cross-script benchmark found the opposite: Japanese OCR accuracy actually exceeds Latin script. The scripts that genuinely struggle are Arabic and Hebrew, and not for the reason most people assume.
Arabic text recognition, that same research found, gets the script right, the model correctly identifies it's looking at Arabic, but still lags on accuracy because visually similar characters within the script get confused with each other. Hebrew has a stranger problem: it gets mistaken for Thai often enough to measurably hurt its scores. Neither of these is "OCR breaks on hard scripts." Both are specific, narrow failure modes that a general claim about multilingual documents completely misses.
That specificity matters because a document pipeline that reads text and then translates it doesn't get to average out these differences. It inherits whichever failure mode its input language has, and if nothing catches the error before translation runs, translation has no way to know the input was already wrong.
Not every script fails the same way
The accuracy gap between scripts is large and well documented. One benchmark comparing OCR performance across language families found character error rates below 2% on Latin and Cyrillic script, climbing past 10% on Perso-Arabic script under the same conditions. That's not a small variance. A 10% character error rate means roughly one character in ten is wrong before any translation step even begins.
The failure modes differ by script for identifiable reasons, not bad luck. Arabic's cursive connectivity means the same letter looks different depending on its position in a word, which is a genuinely harder visual recognition problem than Latin's fixed letterforms. Hebrew and Arabic both read right to left, which affects far more than reading direction: column order in tables, the sequence numbers should appear in, and where a total sits relative to line items all depend on the software correctly reconstructing that direction rather than defaulting to left-to-right assumptions built for English and European languages.
Why the errors don't just add up, they compound
A useful way to think about a document pipeline: OCR reads, then something extracts fields, then possibly something translates. Each stage has its own error rate, and those rates don't add, they compound. A pipeline running at 2% character error rate per stage across a few stages has been observed producing 15 to 20 percent information extraction failure by the time a receipt or invoice reaches a usable state, even though no single stage looks alarming on its own.
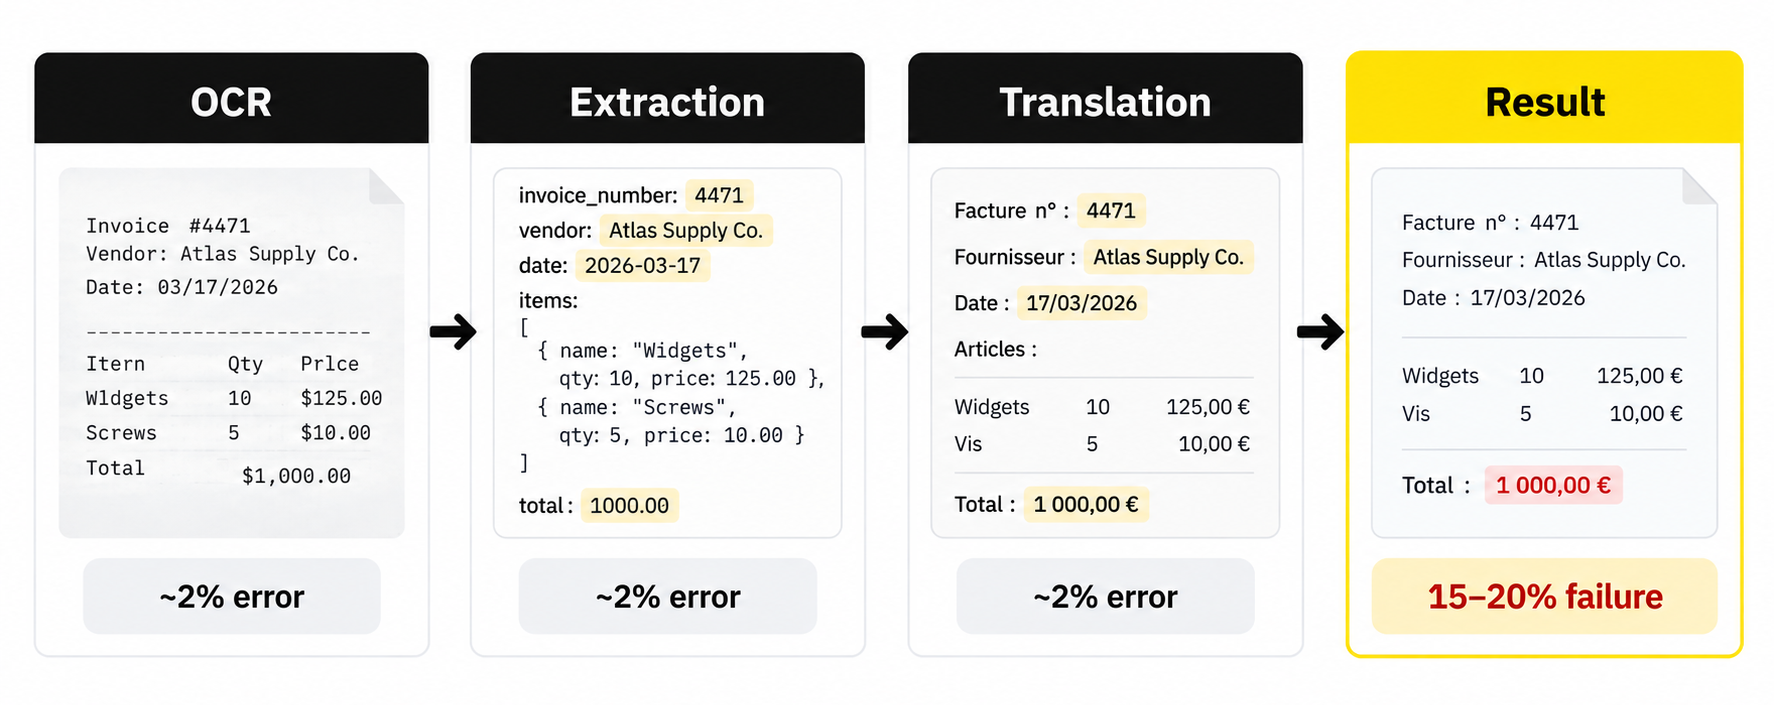
Machine translation makes this worse in a specific way: it doesn't know the text it received already contains an error. A controlled study on OCR-assisted translation for low-resource languages found translation quality degrading measurably as OCR error rate increased, and importantly the relationship wasn't gentle. Translation systems have no mechanism to flag "this input looks corrupted," because a garbled character often still resolves to a plausible-looking word. The error doesn't get caught. It gets translated, which is a version of the same problem our piece on why LLM OCR understands context instead of just reading characters covers from the accuracy side rather than the translation side.
Two failure types that have nothing to do with reading ability
Some of the most common multilingual document failures aren't recognition errors at all. They're formatting and structure problems that persist even when every character was read correctly.
1. Number and currency formatting across locales
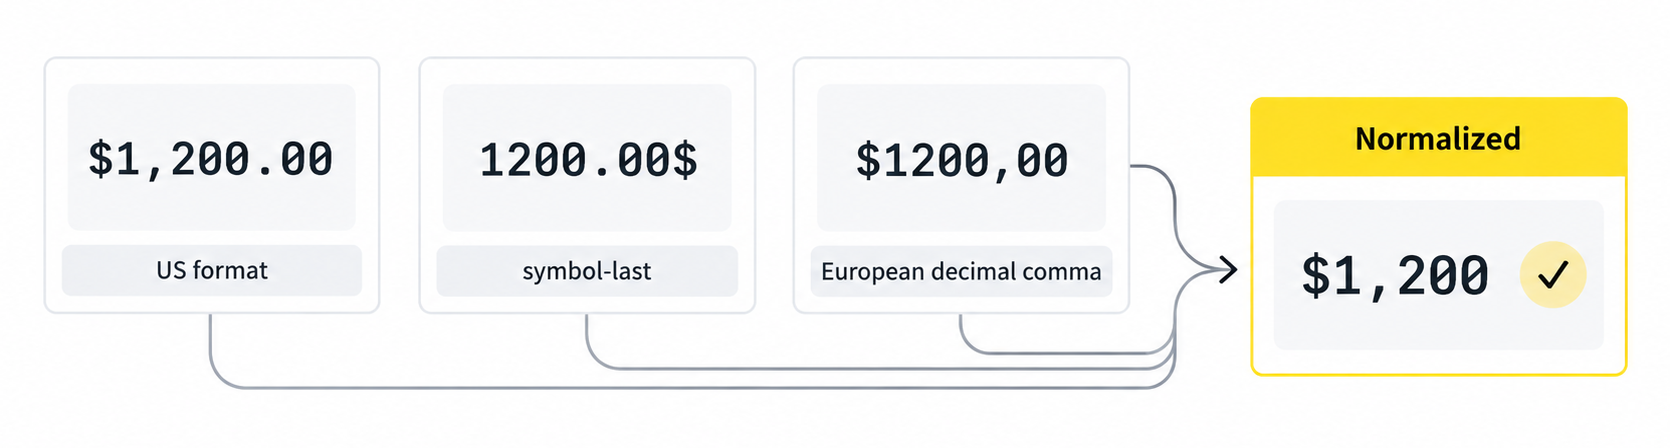
"$1,200.00", "1200.00$", and "$1200,00" all represent the same value. The last one uses the European convention where a comma marks the decimal point rather than the thousands separator. A system that reads all three correctly but doesn't normalize them will treat them as three different, conflicting figures the moment they hit a database or a matching system. This has nothing to do with OCR accuracy and everything to do with whether the pipeline understands that number formatting is locale-specific, not universal.
2. Reading order and table reconstruction
A document in Arabic or Hebrew that includes a table doesn't just need its text read right to left. The columns themselves need to be reassembled in the correct order, the same underlying challenge covered in our guide to table detection and extraction, and a total that sits to the left of line items in a right-to-left layout needs to be recognized as the total regardless of its position on the page. Software built assuming left-to-right layout as the default gets this wrong in ways that look like a translation problem but are actually a layout problem that happened before translation was ever involved.
Where this actually costs money
Currency and unit ambiguity in multilingual documents is a documented, specific failure point in production systems, not a hypothetical. Research on industrial KYC document pipelines processing financial statements across multiple languages found currency unit abbreviations, figures like "IDR'000" or regional terms for thousands and millions, causing genuine magnitude misinterpretation: a value read correctly as text can still end up wrong by a factor of a thousand if the unit abbreviation attached to it isn't correctly parsed.
This is exactly the class of error that matters most in invoice OCR and financial document review, because the number is rarely wrong in an obvious way. A total that's off by three orders of magnitude due to a unit misread doesn't look broken. It looks like a very large or very small invoice, and it can pass a cursory review before anyone checks the source document.
Where each script's specific weakness shows up in practice
An invoice from a supplier using Arabic text recognition inherits the intra-script character confusion described above directly into its line items: a digit or unit price that visually resembles another character doesn't fail loudly, it just becomes a different, plausible-looking number. A Hebrew OCR pipeline handling a right-to-left proof of address runs into the reading-order problem before it ever gets to translation, since the address components have to be reassembled in the correct sequence, not just transcribed correctly in isolation.
Chinese character recognition and Japanese text recognition sit in a different position entirely, and it's worth restating because it cuts against the common assumption: both perform comparatively well against Latin script on current benchmarks, which means a document pipeline that treats "non-Latin script" as a single risk category is misallocating its attention. The documents that actually need the most scrutiny are Arabic, Hebrew, and other scripts with documented intra-script or cross-script confusion, not every script that isn't English.
For identity documents and KYC files specifically, this distinction changes what a review process should prioritize. A Japanese identity document is not automatically higher risk than an English one on recognition grounds alone. An Arabic or Hebrew one, based on the research above, warrants a closer look regardless of how clean the scan looks.
What AI actually fixes, and what it still doesn't
Vision-language models have made real, measured progress on exactly the scripts that struggle most. One comprehensive Arabic OCR benchmark found modern models outperforming traditional engines by an average of 60 percent reduction in character error rate. That's a substantial, real improvement, not a marketing claim.
It is not a solved problem. The same benchmark found the best-performing model still achieving only 65 percent accuracy on Arabic document-to-structured-text conversion. Better than traditional OCR by a wide margin, and still wrong on more than a third of the content. Anyone deploying AI-based extraction on Arabic, Hebrew, or other historically difficult scripts should treat that ceiling as real, not as a rounding error that better prompting will fix.
There's a second, subtler risk that gets worse, not better, as models improve: a modern model's mistakes tend to look more plausible than a classic OCR engine's mistakes. A receipt total misread by a traditional engine often comes out visibly garbled. A vision-language model asked to read the same total can produce a clean, correctly formatted, entirely wrong number, and nothing about the output signals that anything went wrong. Our comparison of AI OCR against traditional OCR covers this failure mode in more depth: it is the same reason confidence scoring matters more as extraction gets smarter, not less.
What has to happen before translation, not after
Fixing this reliably means treating validation as a step that happens before translation touches the text, not a cleanup pass afterward. A few specific mechanisms actually work in production.
Checksum validation catches a meaningful share of numeric errors on its own: if line items are supposed to sum to a stated total and they don't, that's a flag worth raising regardless of what language the document is in. Regex-level sanity checks catch a different class of error cheaply, a date with a thirteenth month or a phone number with the wrong digit count is wrong independent of translation quality. Cross-referencing values against related documents, a purchase order against an invoice, a stated total against a bank statement, catches the errors that pass every check on a single document in isolation.
None of this replaces script-aware OCR or context-aware translation. It sits alongside them, and it's the part most "AI will fix multilingual documents" narratives leave out entirely.
Where Koncile fits
Koncile's extraction runs document classification and script handling before any field extraction begins, which is what makes reading-order reconstruction and layout handling for right-to-left scripts possible in the first place rather than an afterthought applied to already-garbled text. Every extracted number carries a confidence score, so a currency figure with ambiguous unit formatting is flagged as uncertain rather than passed downstream with false precision. Business-rule validation checks totals against line items and cross-references related documents before anything is treated as final.
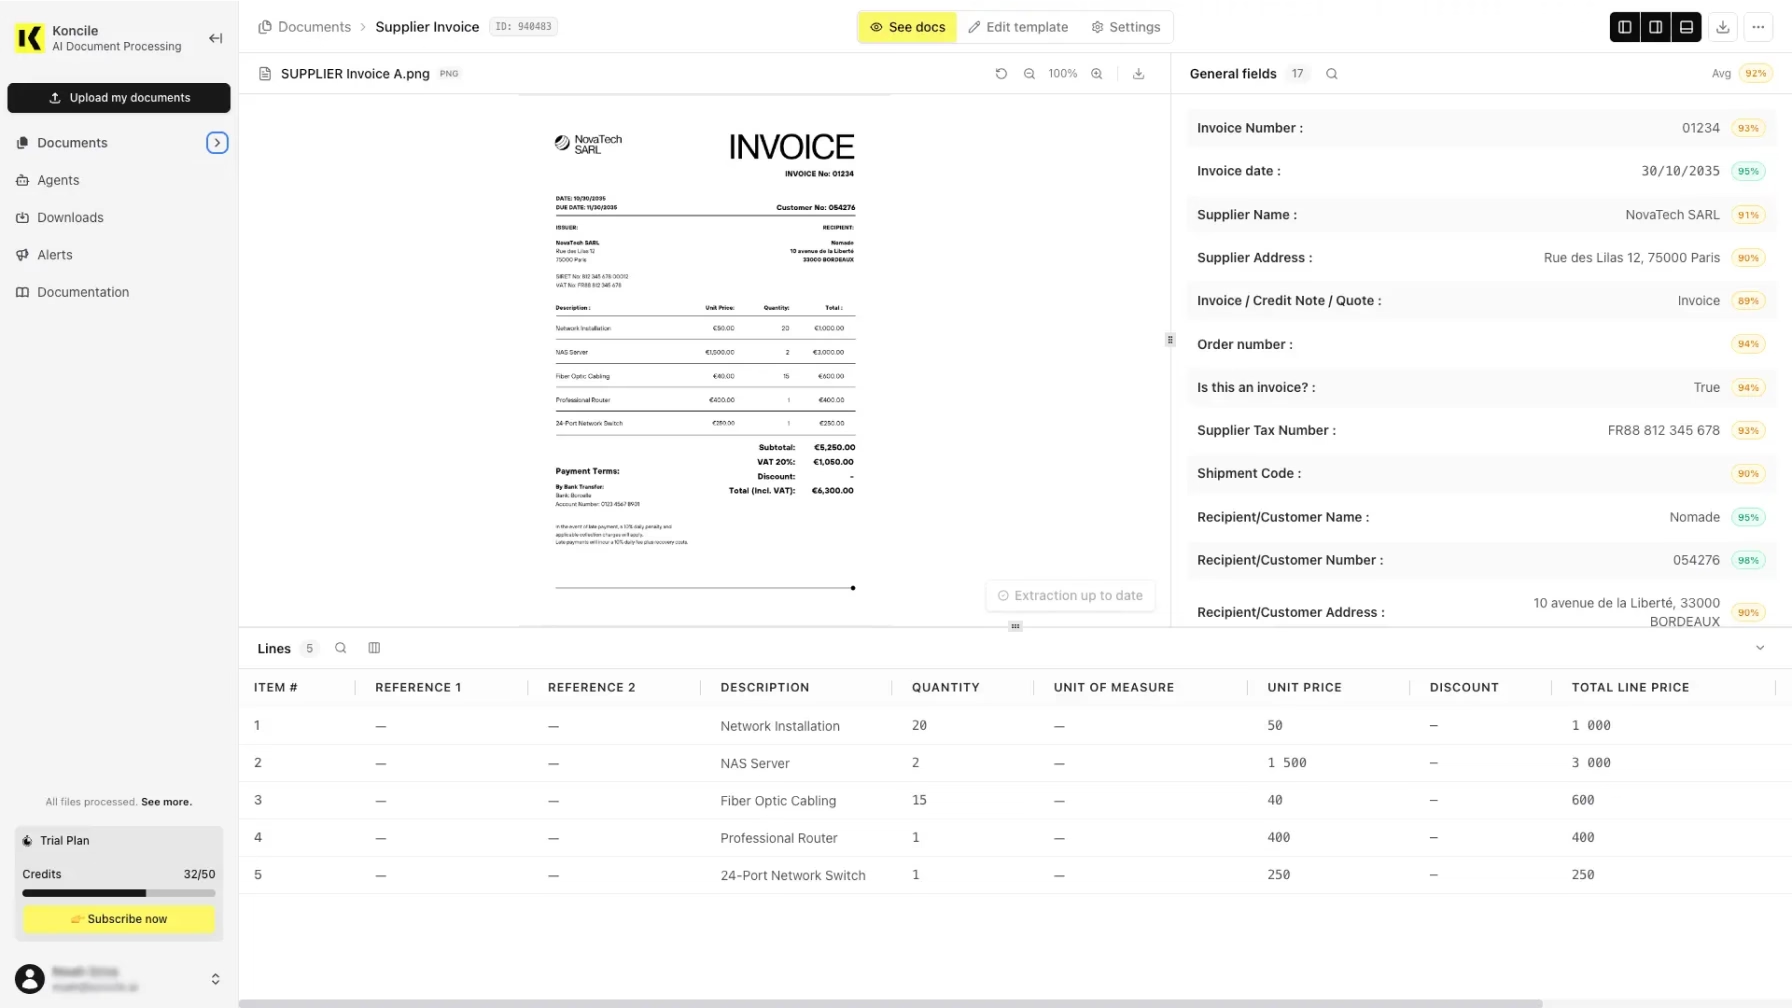
This covers invoices, bank statements, identity documents, and KYC files across the document types and scripts Koncile supports, with the same validation layer regardless of source language. It does not eliminate the underlying accuracy ceiling that current research documents on the hardest scripts. No vendor's marketing claim changes that ceiling. What changes is whether an error gets caught before it reaches accounting, or after.
Your questions about OCR and machine translation for multilingual documents
Sources
- GlotOCR Bench: OCR Models Still Struggle Beyond a Handful of Unicode Scripts. Script-level accuracy variance, Arabic intra-script confusion, Hebrew-Thai cross-script confusion, and Japanese outperforming Latin script.
- KITAB-Bench: A Comprehensive Multi-Domain Benchmark for Arabic OCR and Document Understanding, arXiv 2502.14949. Vision-language models reducing character error rate by an average of 60 percent versus traditional OCR on Arabic, with a 65 percent accuracy ceiling for the best model on document-to-Markdown conversion.
- OCR Improves Machine Translation for Low-Resource Languages, arXiv 2202.13274. Character error rate by script family, and controlled experiments on translation quality degradation as OCR error rate increases.
- A Multistage Extraction Pipeline for Long Scanned Financial Documents: An Empirical Study in Industrial KYC Workflows, arXiv 2604.26462. Currency unit ambiguity causing magnitude misinterpretation in multilingual financial documents.
- The Definitive Guide to OCR in 2026, Edge of Context. Per-stage error compounding in document pipelines and post-OCR validation practices including checksum and cross-reference validation.
- Koncile, AI-Powered OCR vs Traditional OCR. Companion piece on confidence scoring and the silent-failure risk in AI-based extraction.
Real life insights on document automation
5 Best French OCR Solutions to Extract Data from Your Documents
French OCR solutions now make it possible to automatically extract data from your invoices, contracts, and accounting documents using optical character recognition, with hosting based in France. Here is a real comparison of all five OCR solutions, corrected against current 2026 figures where vendor claims had gone stale, covering what actually differentiates them beyond the fact that they are all hosted in France.
Document processing and fraud detection: build or buy?
Extracting and structuring document data, enriching it, detecting fraud: with AI, building your own end-to-end solution has never looked so simple. Buying off the shelf still often turns out to be the better option. Here are the thirty-nine difficulties to expect before you start.
In healthcare, an OCR is judged on what it flags, not on what it reads
Every OCR vendor advertises high accuracy rates, and most of them deliver. On a health document, that is not the right buying criterion. What counts is what the tool does when it is not sure, what it lets you verify, and what it guarantees about the data it handles.

Top Healthcare OCR Tools: HIPAA Compliance and What the Clinical Evidence Shows
Amazon Textract has been formally HIPAA-eligible since October 2019. Most healthcare OCR comparisons never mention that, or check which of the other four tools on their list actually offer a signed BAA. Here is a rebuild that checks compliance status directly, and looks at what the real clinical trials on ambient AI scribes actually found, not just what the marketing claims.
Best Accounting Software for Sole Proprietors and Freelancers in 2026
A freelancer sending a dozen invoices a month can blow through Xero's cheapest plan by week three, and a $19-a-month FreshBooks account caps out at five clients. The number on a pricing page is rarely the number you actually pay. Here is a real comparison of QuickBooks, Xero, Wave, and FreshBooks built for a business of one, not a growing team.