What Is OCR Used For? Everything You Need to Know
PDFs or images hide valuable data-OCR frees it from invoices, contracts, receipts, and more for business use.
Learn how OCR turns your PDFs and images into structured data. What technologies should I use? What are the costs and the accuracy? Make the right choice with our guide.
Invoices, purchase orders, delivery notes, contracts, quotes, rent receipts, bank statements, certificates... When you have documents in PDF or image format, the data is “trapped” and unusable for the business. However, thanks to OCR software, you can convert your unstructured documents into structured information, saving you time in your operations.
With generative AI, OCR software have made significant advancements.
Traditional Methods: Machine Learning & Supervised Learning
OCR allows for the processing of a digital image to extract textual data, which can include enhancements (font, bold, titles, layout). Traditionally, OCR analysis links on several layers of processing:
- Image Pre-analysis: The image definition is improved using filters; the image is straightened and cropped.
- Text segmentation: Each block of text is located on the image relative to others.
- Character Recognition: Each character is compared to a library of shapes for identification, especially using neural network analyses.
- Recognition of Forms, Tables, and Associated Values: a feature commonly found in Invoice OCR tools such as Amazon Textract.
- Post-processing: Based on statistical rules, errors are eliminated.
However, there are two limitations to supervised learning:
- Lack of Language Understanding: The machine does not consider the meaning of the extracted words, which affects the quality of extraction. More complex documents (e.g., quotes or contracts) often yield errors.
- Exception Management: As the learning is done on a limited number of documents, there are often rare cases that the AI has not yet encountered.
The Revolution of LLMs: Precision and Customization
OCR primarily relied on supervised learning: machines were trained by manually labeling results on images. Now, with the advent of LLMs, we’ve entered the age of intelligent document processing, where results are significantly better. This means machines learn generically, without the need for precise labeling. The results are significantly better, with increased accuracy and the ability to process complex documents without the intensive human intervention previously required.
Comparison of Computer Vision & LLMs
Here's a comparative table of performance differences between OCRs based on computer vision and those based on LLMs. The document processing technology Koncile combines the best of both to achieve optimal results.
PDF, JPEG, PNG, Scanned or Photo Documents: What are the Differences?
Searchable PDF
Your PDF file was created by software, allowing you to select text within the document. This is referred to as a “searchable” PDF. Verdict: In this case, character recognition will not be necessary as the plain text already exists in the file. However, the “layout” must be captured to prioritize the information.
Scanned PDF from Paper Document
The PDF file does not contain textual information. The OCR software must perform character recognition and layout detection. The file type (PDF, PNG, or JPEG) is generally indifferent for processing.
Photo Document
Similar to a scanned PDF, character recognition and layout steps are necessary. Be aware, there is a greater risk of errors.
Electronic Format or EDI
For invoices, typical formats like “Invoice-X” are PDFs attached to an XML file. The information is then directly usable in a database. However, the PDF file may often contain more information than the XML file, particularly line-by-line invoice information.
Document with Handwriting
Detection of signatures is currently yielding very good results. OCR handwriting recognition varies: uppercase letters are well captured, but cursive writing may lead to errors.
What Documents Can Be OCred?
To answer this question, two criteria should be closely examined:
- Document Variability: If documents always contain the same information in the same format, capture will be easier.
- Document Length: Short documents are easily processed; as document size increases, confusion among various pieces of information can occur.
Short Documents with Relatively Standardized Information
Short Documents with Variable Formats and Repeated Information:
Long Documents Composed of Multiple Parts
- Contracts
- Medical prescriptions & documents
- Expert reports
- Customs documentation
- Tax documents
- Real Estate Files
What Information Can Be Captured in a Document?
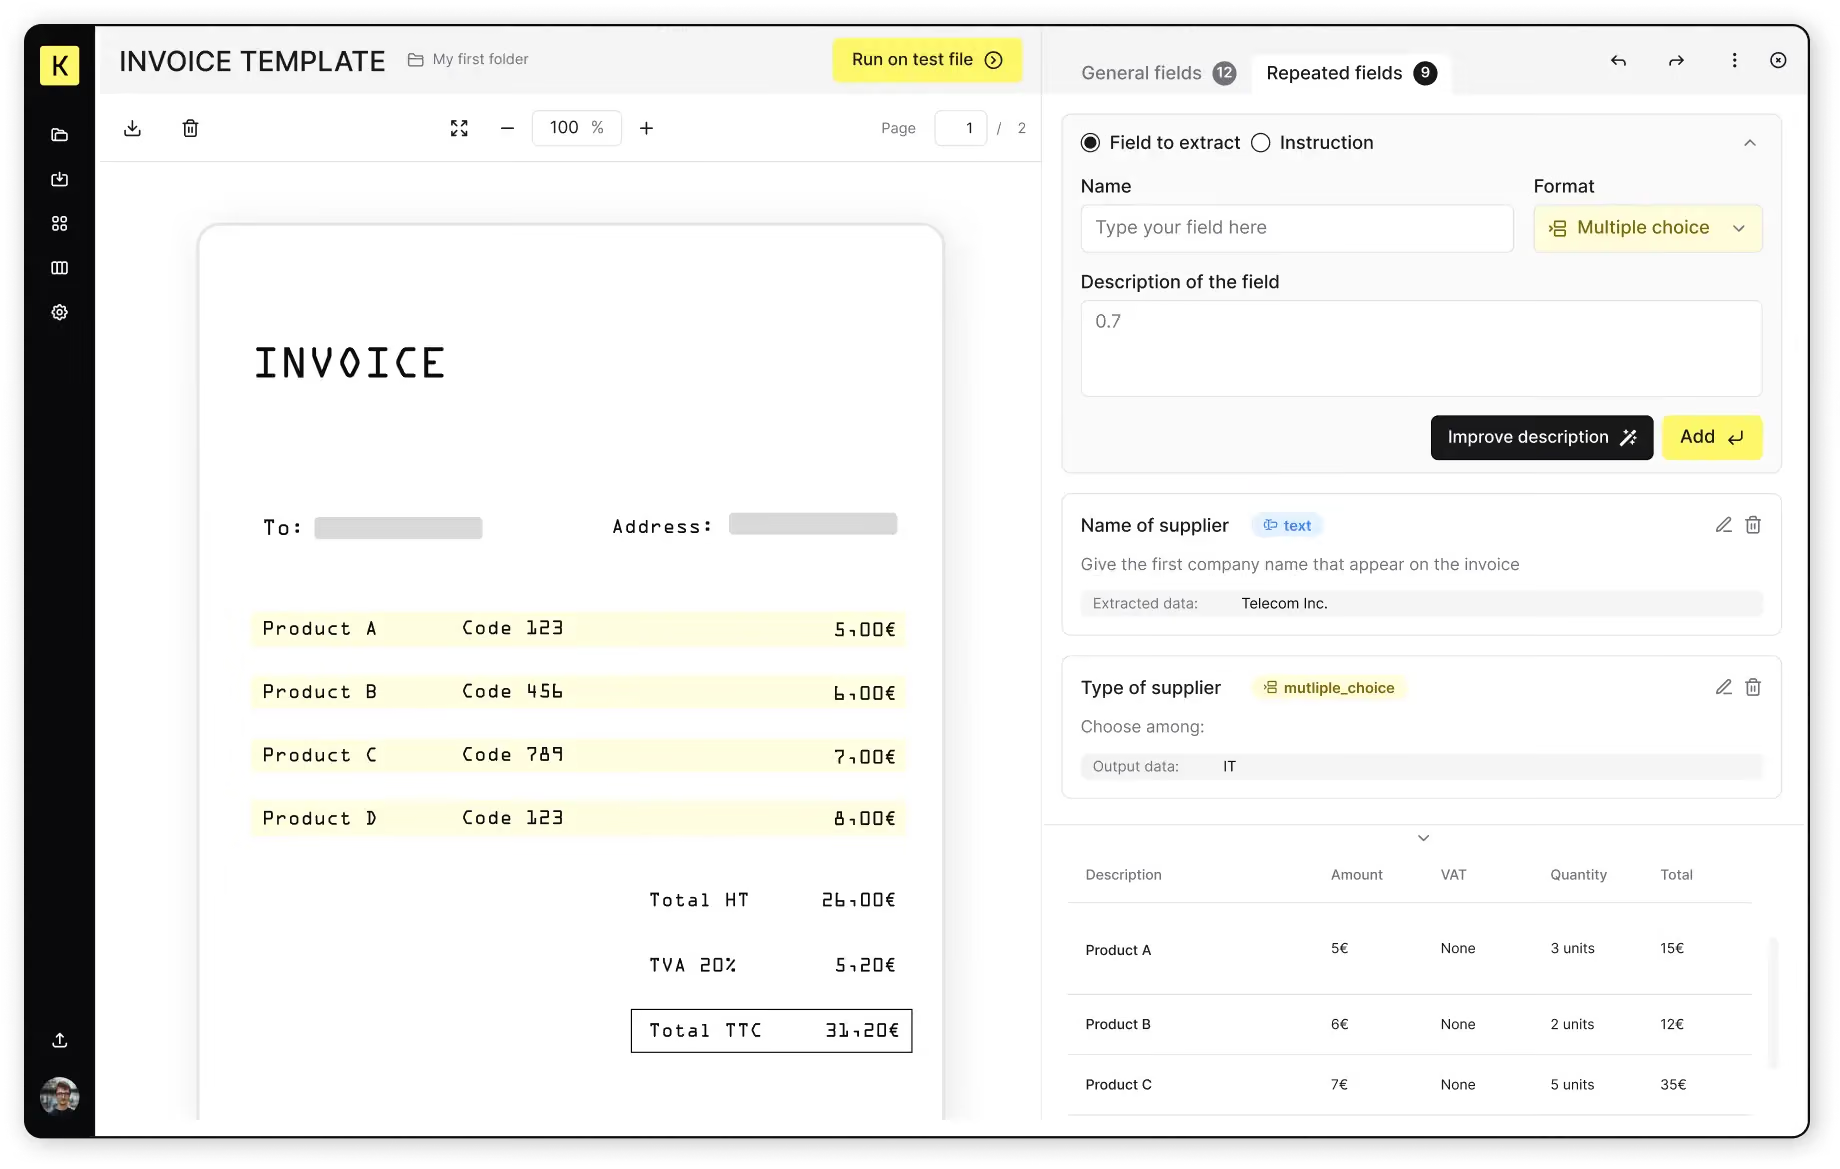
OCRs provides a standard list for each type of document. With LLMs, you can now go further by defining the fields that make sense for your use case. The Koncile platform allows you to specify fields to extract in a No-code manner. To improve accuracy, it may be useful to indicate an example of the desired result.
Test a Trial version of Koncile and compare results with traditional OCRs.
What are the Costs of OCR?
The cost of OCR can vary from 1 cent to 20 cents per page.
There are also Free Libraries Available for Character Extraction, Such as the Tesseract library, now sponsored by Google, or the open-source GOCR library written in C, which works on Linux, Windows, and MacOS.
What is the Average Accuracy of an OCR?
OCR accuracy varies by software provider. Currently, line-by-line extraction remains a challenging point.
Discover our complete comparison of different OCR solutions.
What is the Processing Time for an OCR?
Processing Time Can Range From hath Few seconds to 1 minute, depending on the type of OCR used.
Processing time is influenced by the complexity and length of the document and the resolution of the image. Multi-processing approaches, including text detection and LLMs, may extend processing time while improving overall accuracy.
Real life insights on document automation
Why Do OCR & Machine Translation Fail Without AI?
Japanese combines three writing systems on one page and should be a hard case for OCR. Benchmark research found the opposite: Japanese accuracy exceeds Latin script. Arabic and Hebrew are where things genuinely go wrong, for specific, documented reasons. Here is what real research shows about why scripts fail differently, and what actually stops the errors before translation compounds them.
How to Detect a Fake Bank Statement: Our 9 Methods
Bank statements are one of the documents most exposed to fraud. At Koncile, we detect up to 1.4% of edited or tampered statements in a set of 150,000 statements. AI generated deepfakes get a lot of attention, but focusing only on them today would be a mistake.
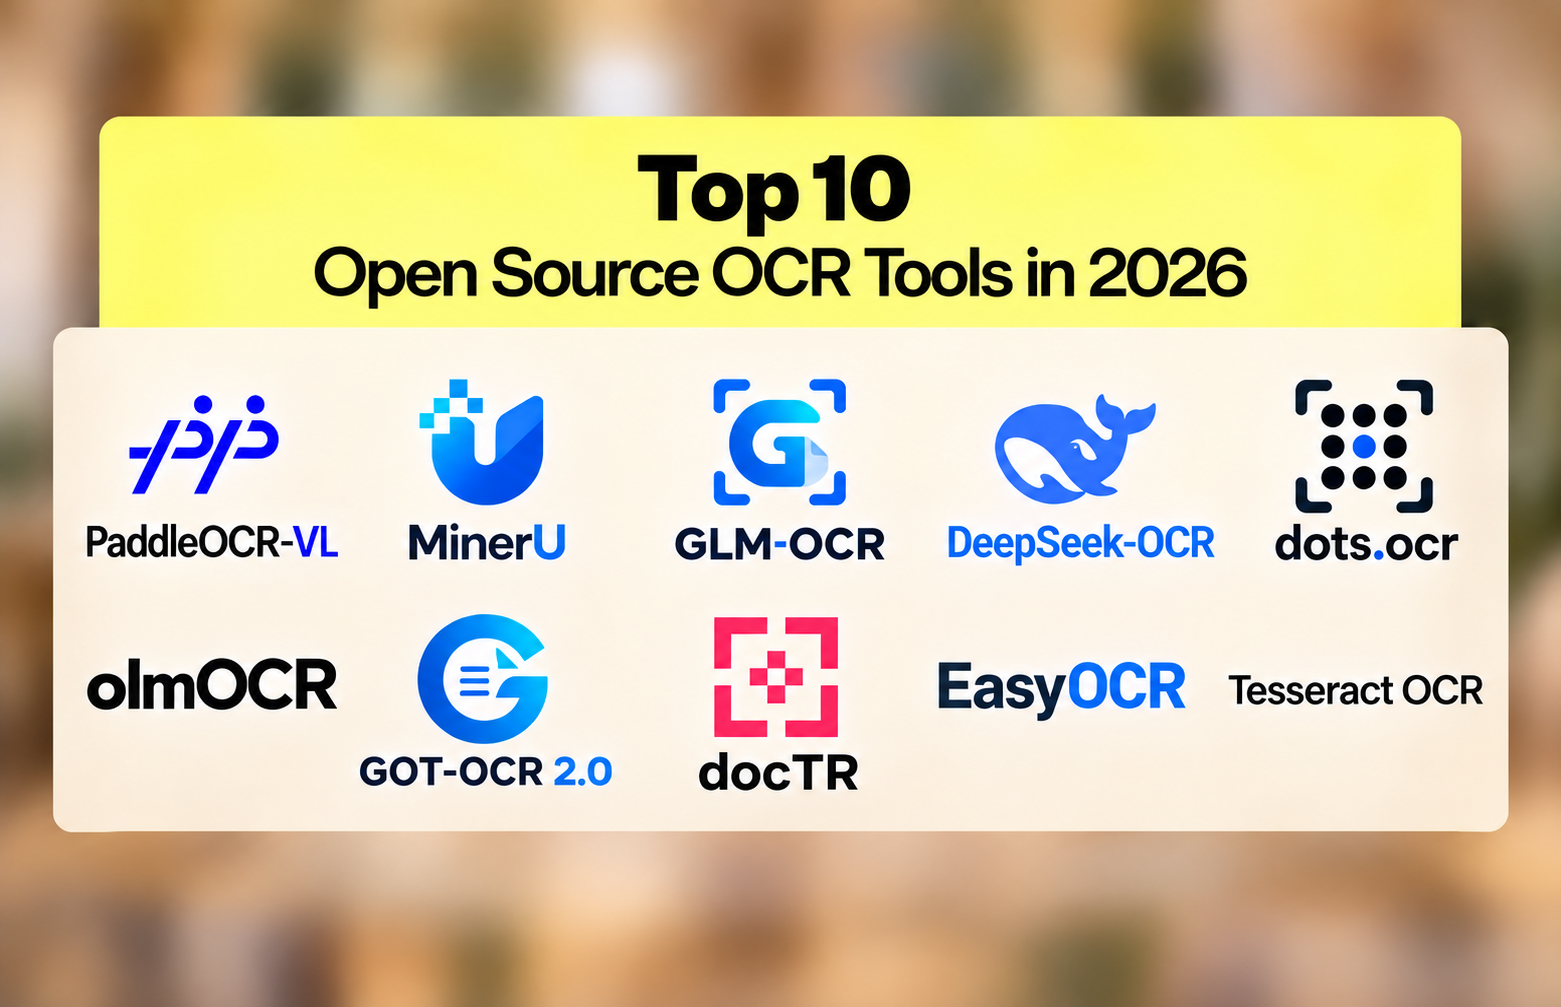
10 Best Open Source OCR Tools in 2026
The open source OCR ranking inverted in the past eighteen months. A 0.9-billion-parameter model now reads documents more accurately than a 235-billion-parameter one. PaddleOCR-VL scores 96.34% on OmniDocBench v1.6; Qwen3-VL-235B scores 89.78%. Here are the 10 best open source OCR engines in 2026 and how to pick between them.
Top 10 Document Fraud Detection Software in 2026
Every accuracy figure in this market is self-reported and none has ever been independently verified. Meanwhile forgery services sell documents built specifically to defeat named detection vendors, openly, on the indexed web. Here is our comparison of the 10 best document fraud detection software platforms and the five weaknesses that separate them.
Tesseract OCR: is it still the best open-source OCR in 2026?
Among the many solutions available on the market, Tesseract is often cited as one of the best open-source OCR tools. But is it still the best solution in 2026? We analyse its performance, strengths, limitations, and open-source OCR alternatives.